Work / An image model paints, a character describes what it sees, and that description becomes the next painting.Visual Whispers: picture telephone
The idea
Visual Whispers was one of my first experiments combining LLMs and diffusion models in an app. I used the game of telephone: each participant passes on their own interpretation, and the story changes along the way.
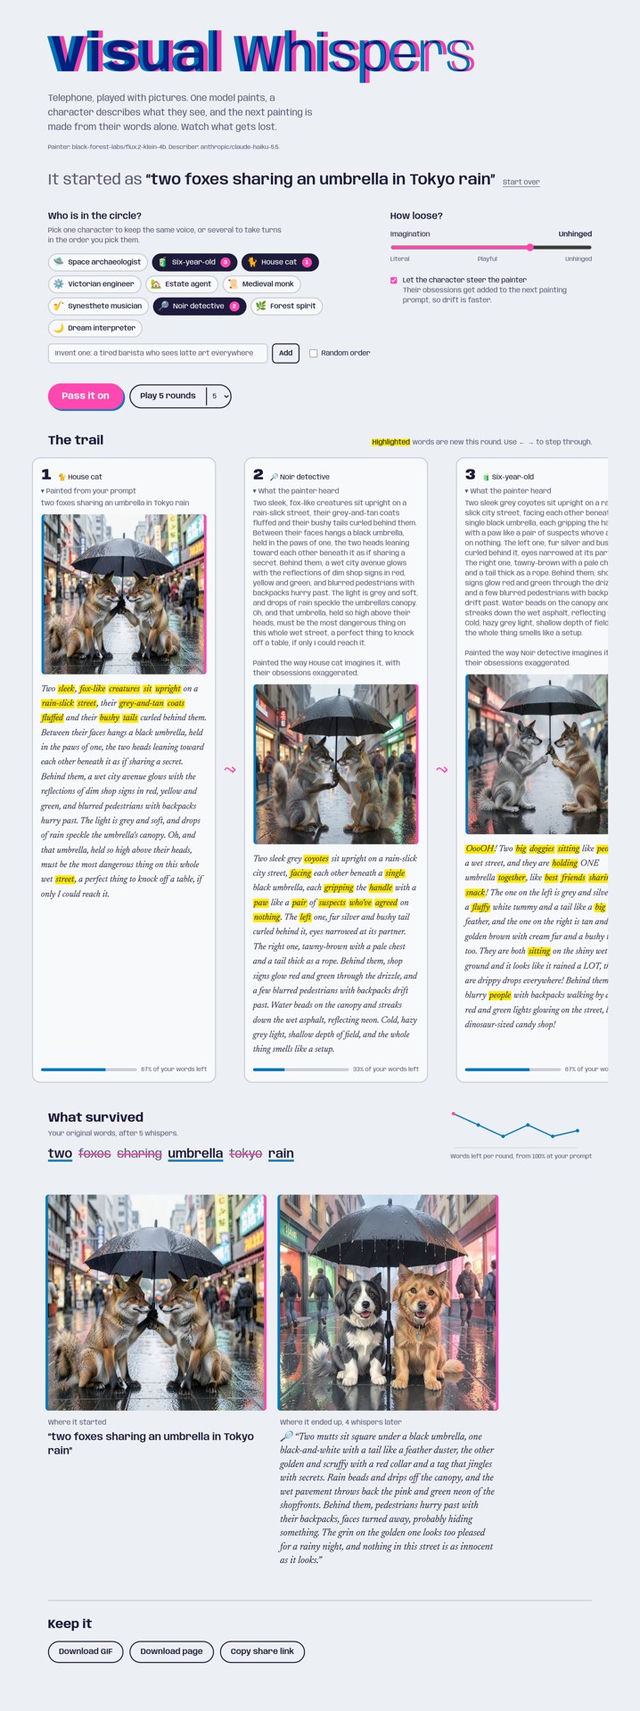
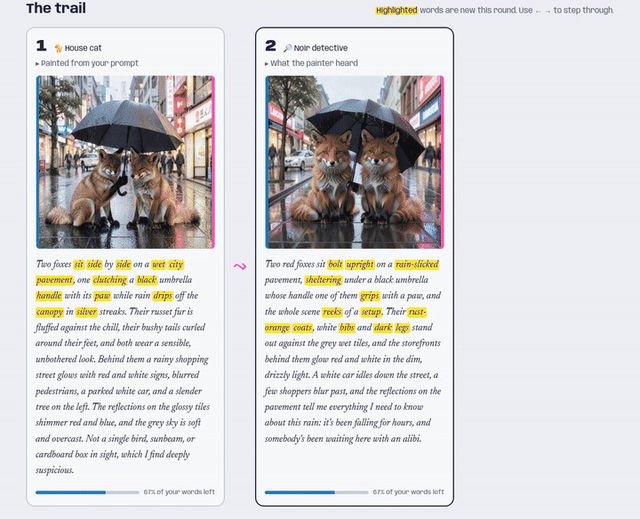
Here, an image model paints your prompt. A vision model looks at the painting through a character's eyes and describes it. The next painter receives only that description. After a few rounds, you can see which details survived and what the models invented.
Making it playable
You can keep one character throughout or let several take turns. A house cat notices different things from a noir detective. An imagination control changes the instructions and model temperature, and an optional setting lets the character's interests influence the next painting prompt.
Each round streams onto the page: first the image, then the description. New words are highlighted, and a small indicator tracks how many words from the original prompt remain. It is a word-overlap measure, not a test of whether the meaning survived.
Connecting the models
The current app uses OpenRouter for vision-language descriptions and image generation, with an optional Replicate path for FLUX. The Python backend streams progress to the TypeScript interface through Server-Sent Events and stores the images so that exports do not depend on temporary provider URLs.
A chain can be saved as a GIF, a self-contained web page or a share link. The app also has an offline demo with stand-in models for trying the interaction without an API key.